Cloud data lake replacing legacy Oracle infrastructure
Vendor lock-in eliminated, query times from days to hours
days→hoursquery latency
01Challenge
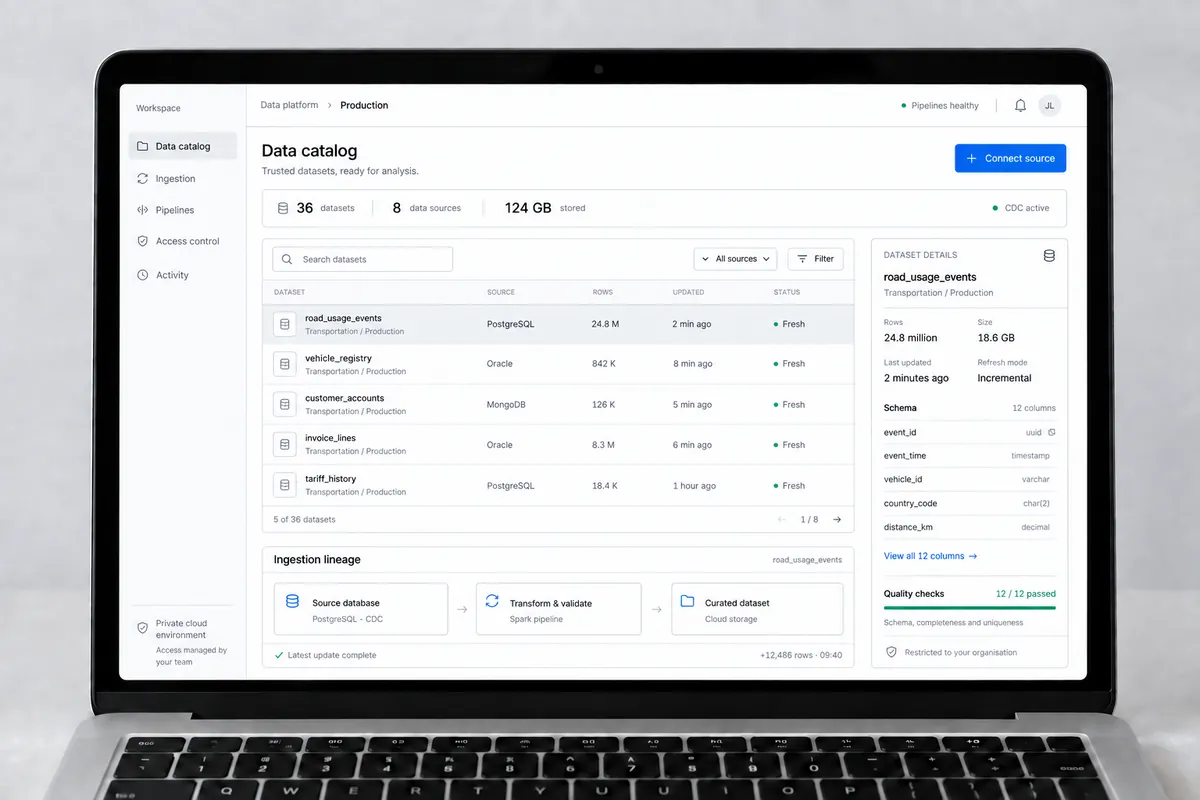
Multiple fragmented databases (MongoDB, PostgreSQL, and legacy systems) feeding analytics that took days to run. The Oracle-centric architecture created hard vendor lock-in. The operator needed to unify its data sources into a single platform, eliminate that lock-in, and bring query times down from days to hours, without losing any of the historical data accumulated over years of operation.
02The DNA Solutions approach
A full cloud migration to AWS in three phases. First, an assessment of the existing infrastructure to map constraints and dependencies. Second, complete historical extraction enriched and validated through modern Change Data Capture (CDC) techniques. Third, rigorous validation: verification scripts compared the cloud platform against the original databases row by row before cutover.
The platform runs Apache Spark pipelines with IAM-based security controls and encryption standards throughout. Delivered as a co-development engagement: DNA and the client team operated as a single data intelligence unit, with explicit knowledge transfer to leave the client autonomous.
03Outcomes
- Query processing reduced from days to hours
- Fragmented MongoDB / PostgreSQL / legacy sources unified into a single Data Lake
- Vendor lock-in on Oracle eliminated
- Client team transitioned from analysts to autonomous data engineers